Our Vision
Democratizing AI Infrastructure
Break down barriers and make high-performance AI computing accessible to every innovator, regardless of size or location—empowering startups, academic institutions and enterprises.
PT. POLIDISTER INNOVATIONS GROUP
A leading provider of high-performance AI computing solutions in Indonesia, delivering enterprise-grade GPU infrastructure for artificial intelligence, machine learning and deep learning workloads.
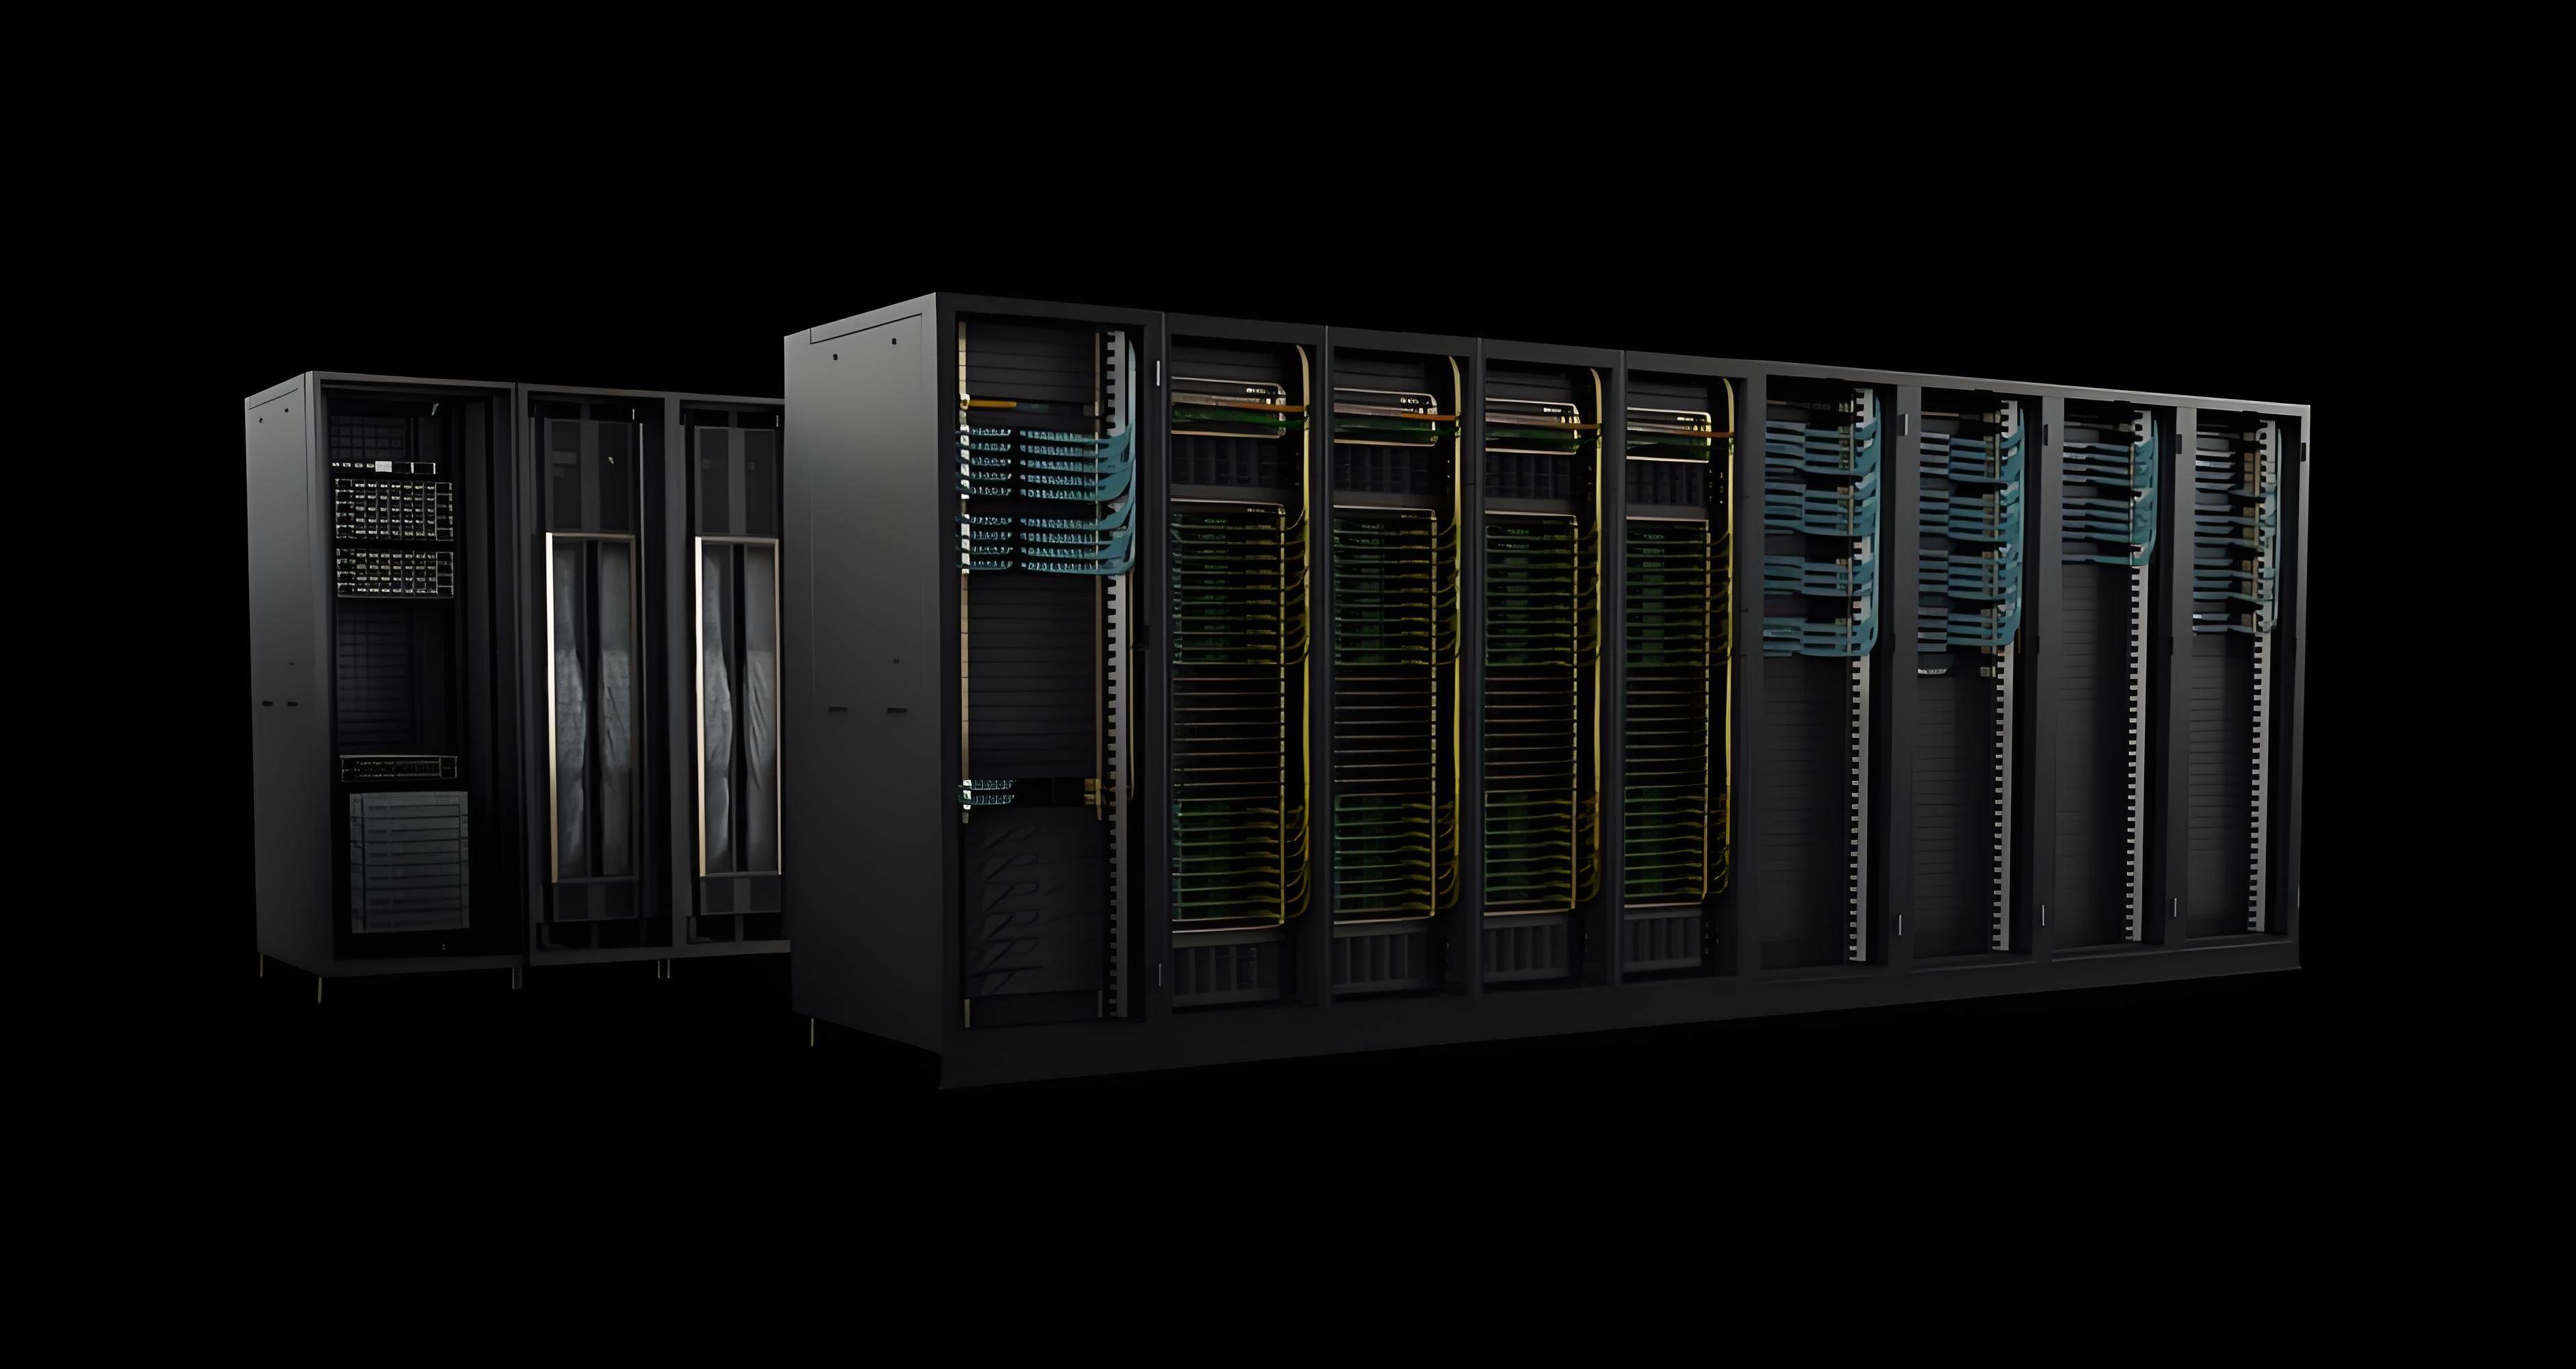
Established in 2024, PT. Polidister Innovations Group specializes in enterprise-grade GPU infrastructure that powers AI, machine learning and deep learning workloads.
We serve businesses, researchers and innovators across Southeast Asia, bridging the gap between technological potential and real-world application.
Break down barriers and make high-performance AI computing accessible to every innovator, regardless of size or location—empowering startups, academic institutions and enterprises.
Deliver robust, flexible and affordable enterprise-grade GPU infrastructure that accelerates AI workloads and digital transformation across Southeast Asia.
Four advantages defined in the company profile support faster experimentation, deployment and scale.
Powered by next-generation NVIDIA B300 Tensor Core GPUs, delivering breakthrough AI performance with exceptional compute efficiency and accelerated model training capabilities for large-scale generative AI, LLMs, and high-performance computing workloads.
A flexible pay-as-you-go model eliminates heavy upfront capital expenditure and allows customers to pay only for the compute resources they consume.
Pre-configured GPU clusters reduce lengthy procurement and setup cycles, enabling access within hours rather than weeks.
Resources can scale up for large training jobs or down for testing phases, reducing overprovisioning and wasted capacity.
Q4 2026
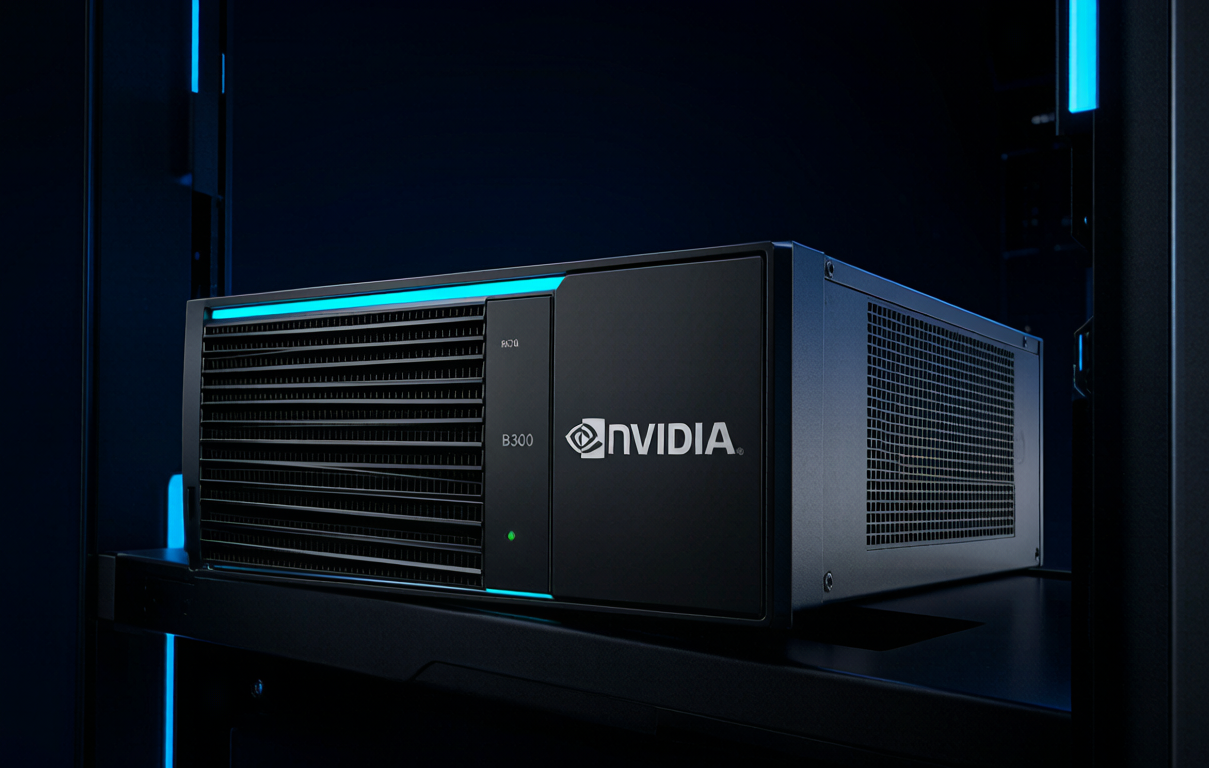
Expanding Polidister's AI infrastructure with NVIDIA B300 accelerated computing platforms.
Supporting large-scale LLM training, generative AI, inference and high-performance computing workloads.
Project delivery and operational readiness are targeted for Q4 2026.
Building the next generation of AI infrastructure capacity across Indonesia and Thailand
The platform supports model development, production services, scientific simulation and enterprise analytics.
Pre-training and fine-tuning large language models with billions of parameters.
High-throughput, low-latency model serving for production-grade applications.
Image and video recognition, object detection and semantic segmentation.
Climate modeling, drug discovery, molecular dynamics and material science.
Diffusion models and text-to-image or video synthesis for content creation.
Financial risk modeling, seismic exploration and large-scale data analytics.
High-density AI infrastructure requires power, cooling, rack loading, connectivity and operating procedures to be planned as one readiness program.
Validate utility capacity, UPS and distribution, cooling strategy, floor loading, rack density and environmental conditions against the GPU cluster design.
Confirm delivery routes, staging, access control, remote-hands coverage, maintenance windows, spares handling and escalation paths.
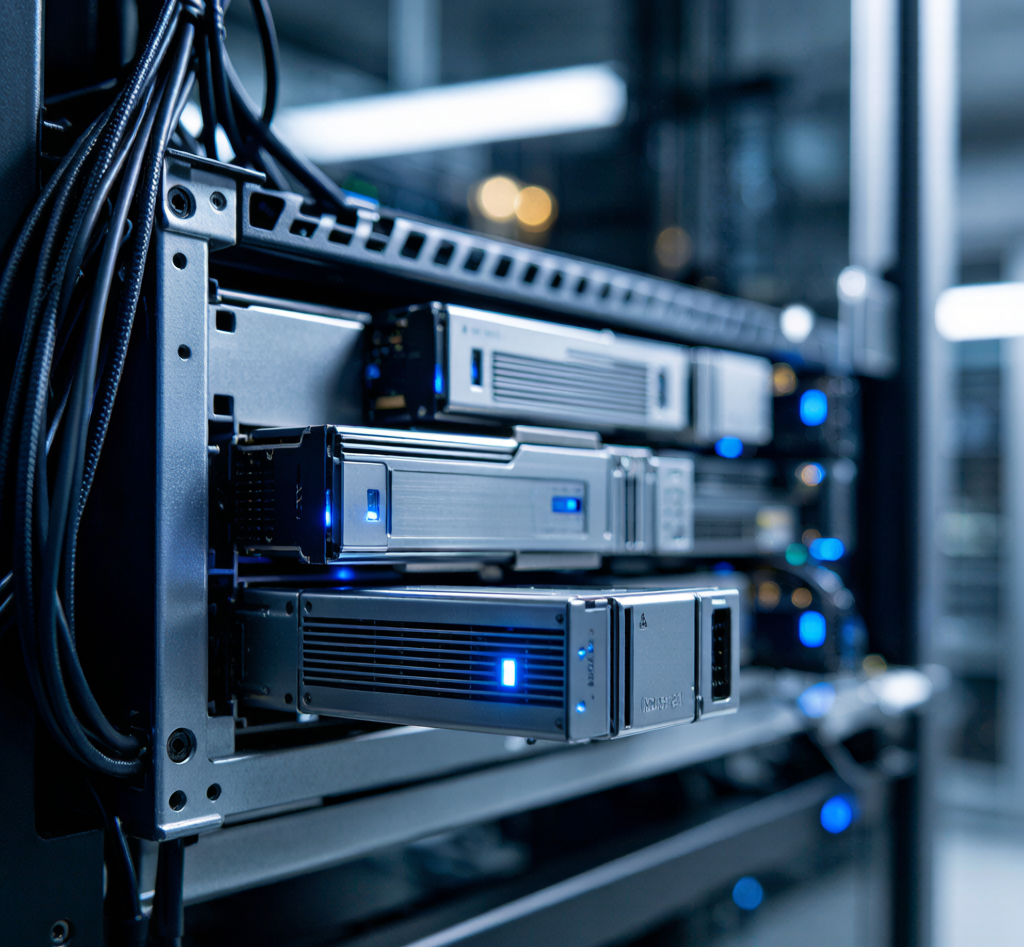
Receive, inspect and install GPU servers, switches, storage and supporting nodes to the approved rack and power plan.
Build and label power, management and high-speed connections with documented port maps and cable routes.
Configure InfiniBand or high-speed Ethernet topology, then validate link state and redundancy.
Coordinate vendors, data-center operations and customer teams across logistics, installation and change control.
Integration aligns firmware, drivers, network fabric, storage, orchestration, security and performance before production use.
Align BIOS, BMC, GPU and switch firmware plus approved settings across every node.
Install and validate the OS, NVIDIA drivers, CUDA libraries, container runtime and workload dependencies.
Confirm topology, bandwidth, latency, redundancy and error-free GPU-to-GPU links.
Verify data paths, permissions, throughput and checkpoint behavior under load.
Configure scheduling, resource allocation, monitoring, access control and customer environments.
Run burn-in and benchmarks, isolate bottlenecks and tune compute, network and storage.
Verify facility capacity, inventory, firmware, cabling, security controls and operating procedures.
Check node health, GPU status, network paths, storage, monitoring, alerting and failover.
Execute burn-in, stress and representative AI workloads; record throughput, latency and stability.
Deliver as-built records, configuration baselines, runbooks, acceptance evidence and operator training.
Managed operations cover monitoring, response, maintenance, spares, reporting and planned evolution.
Track hardware health, environmental conditions, fabric errors, capacity and service alerts.
Triage faults, coordinate remote hands and vendors, document impact and restore service.
Plan inspections, firmware reviews, component checks and controlled maintenance windows.
Maintain critical-spares visibility and coordinate replacement through validation.
Provide utilization, incident, availability and maintenance reporting for governance.
Plan upgrades, compatibility reviews, capacity expansion and end-of-life actions.
Structured and delivered a 256-unit NVIDIA H100 AI-compute service framework.
Experience across capacity planning, infrastructure coordination and managed operations.
Planning 128 NVIDIA B300 systems in Indonesia with an initial plan of approximately 2.25 MW.
Final scope and schedule remain subject to engineering, supply, contracts and approvals.
Contact PT. Polidister Innovations Group for inquiries, support and potential collaboration.
Rukan CBD, Jl. Green Lake City Boulevard NO.F27, RT.006/RW.008, Petir, Cipondoh, Tangerang City, Banten 15146
+62 882 2025 8888
Available Monday to Friday, 9 AM – 6 PM (WIB)
CS@polidister-ai.com
We typically respond within 24
business hours.
“We value your feedback and are committed to providing you with the best support possible. Let’s connect and build something great together.”